AI Datacenter in a Desktop Box
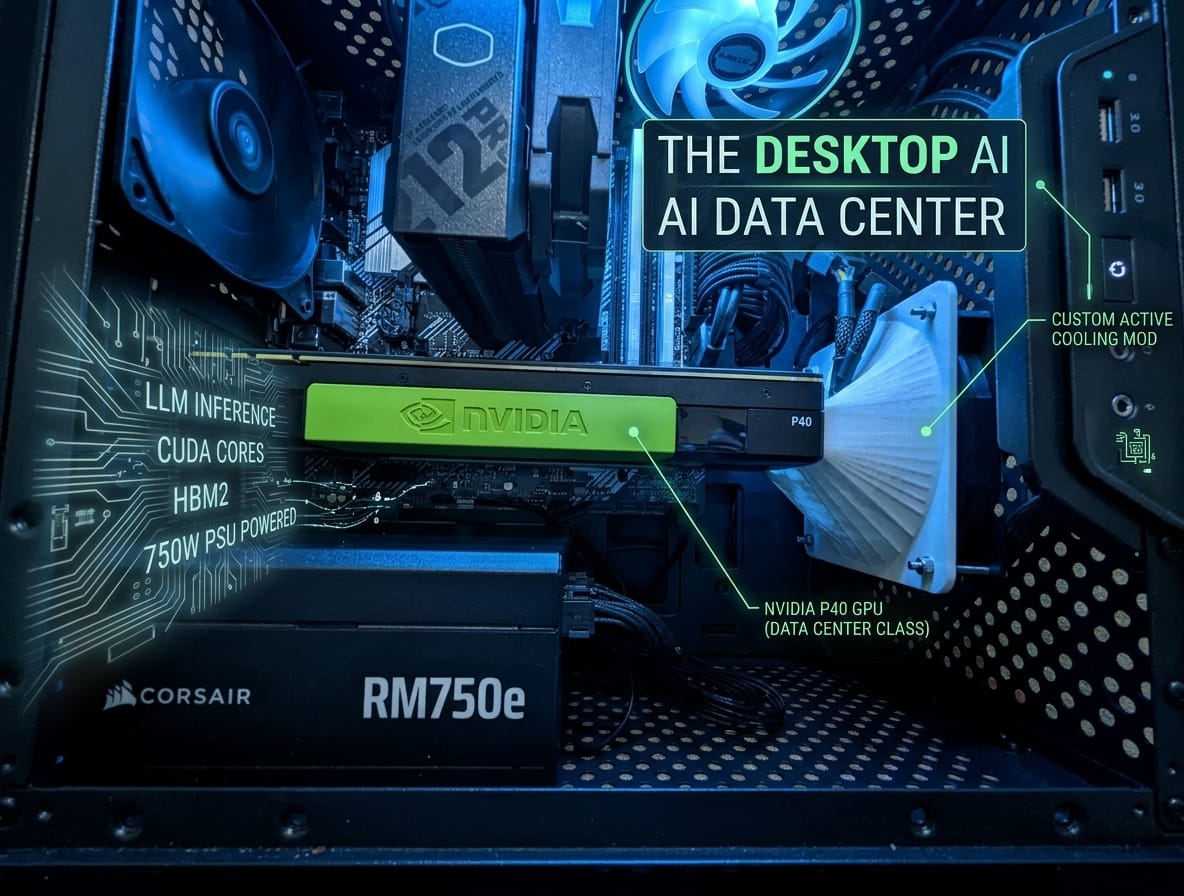
Here's another fresh build I finished over the weekend.
This is another build done on a tight budget and spare parts. I would say this roughly cost me around $550 - $600. The price to performance here screams value and has no right being so powerful. I'm super happy with it!
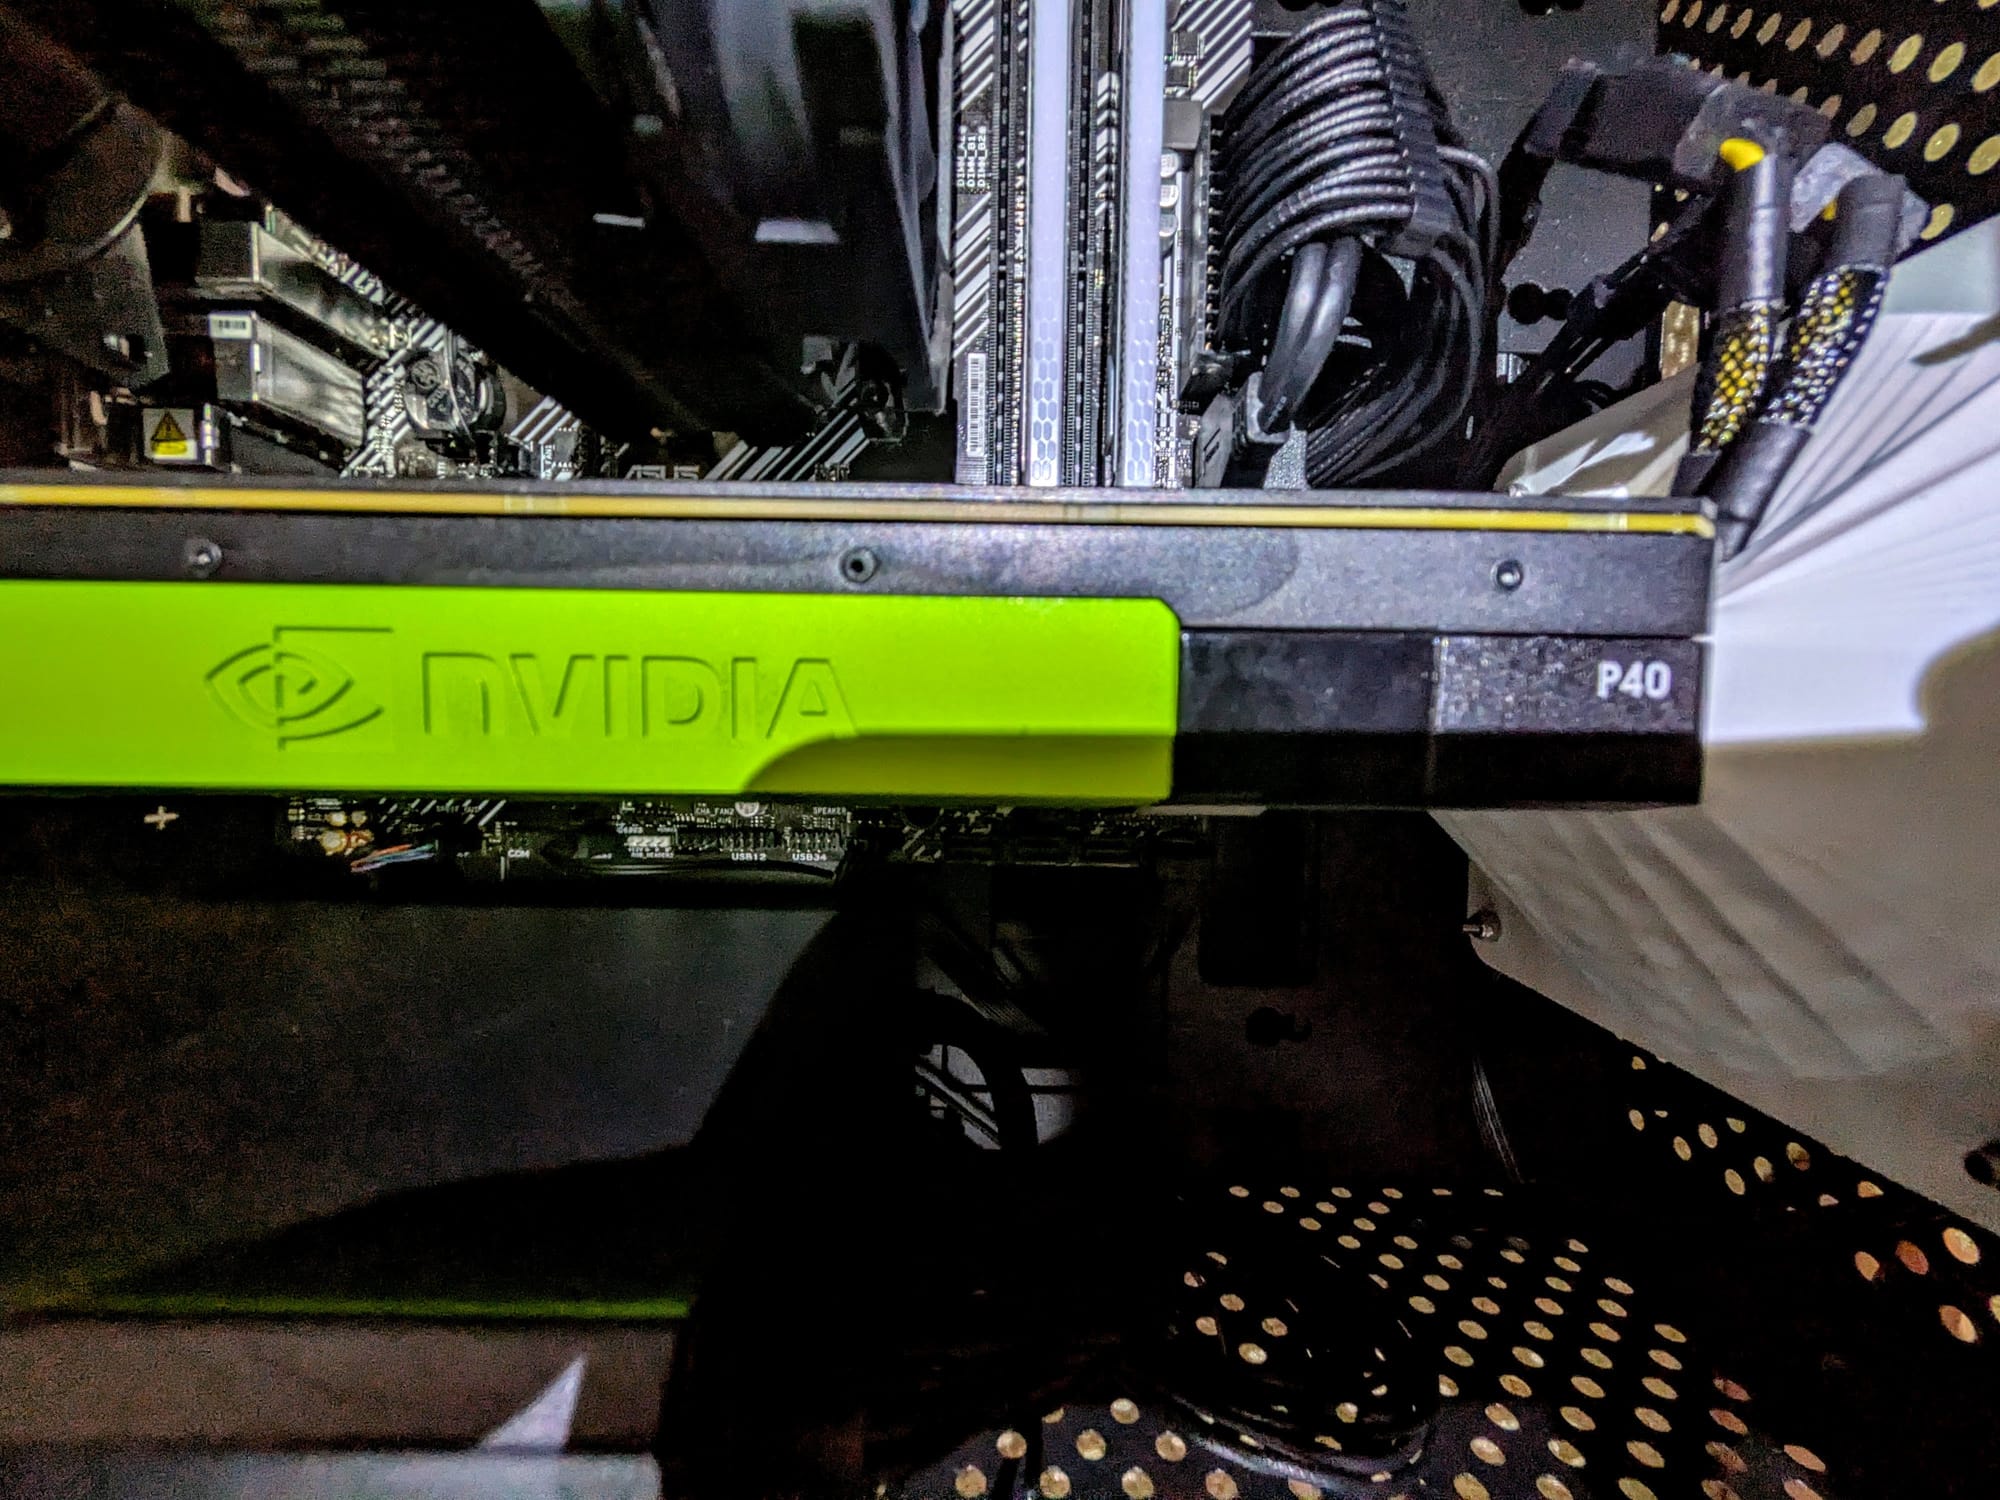
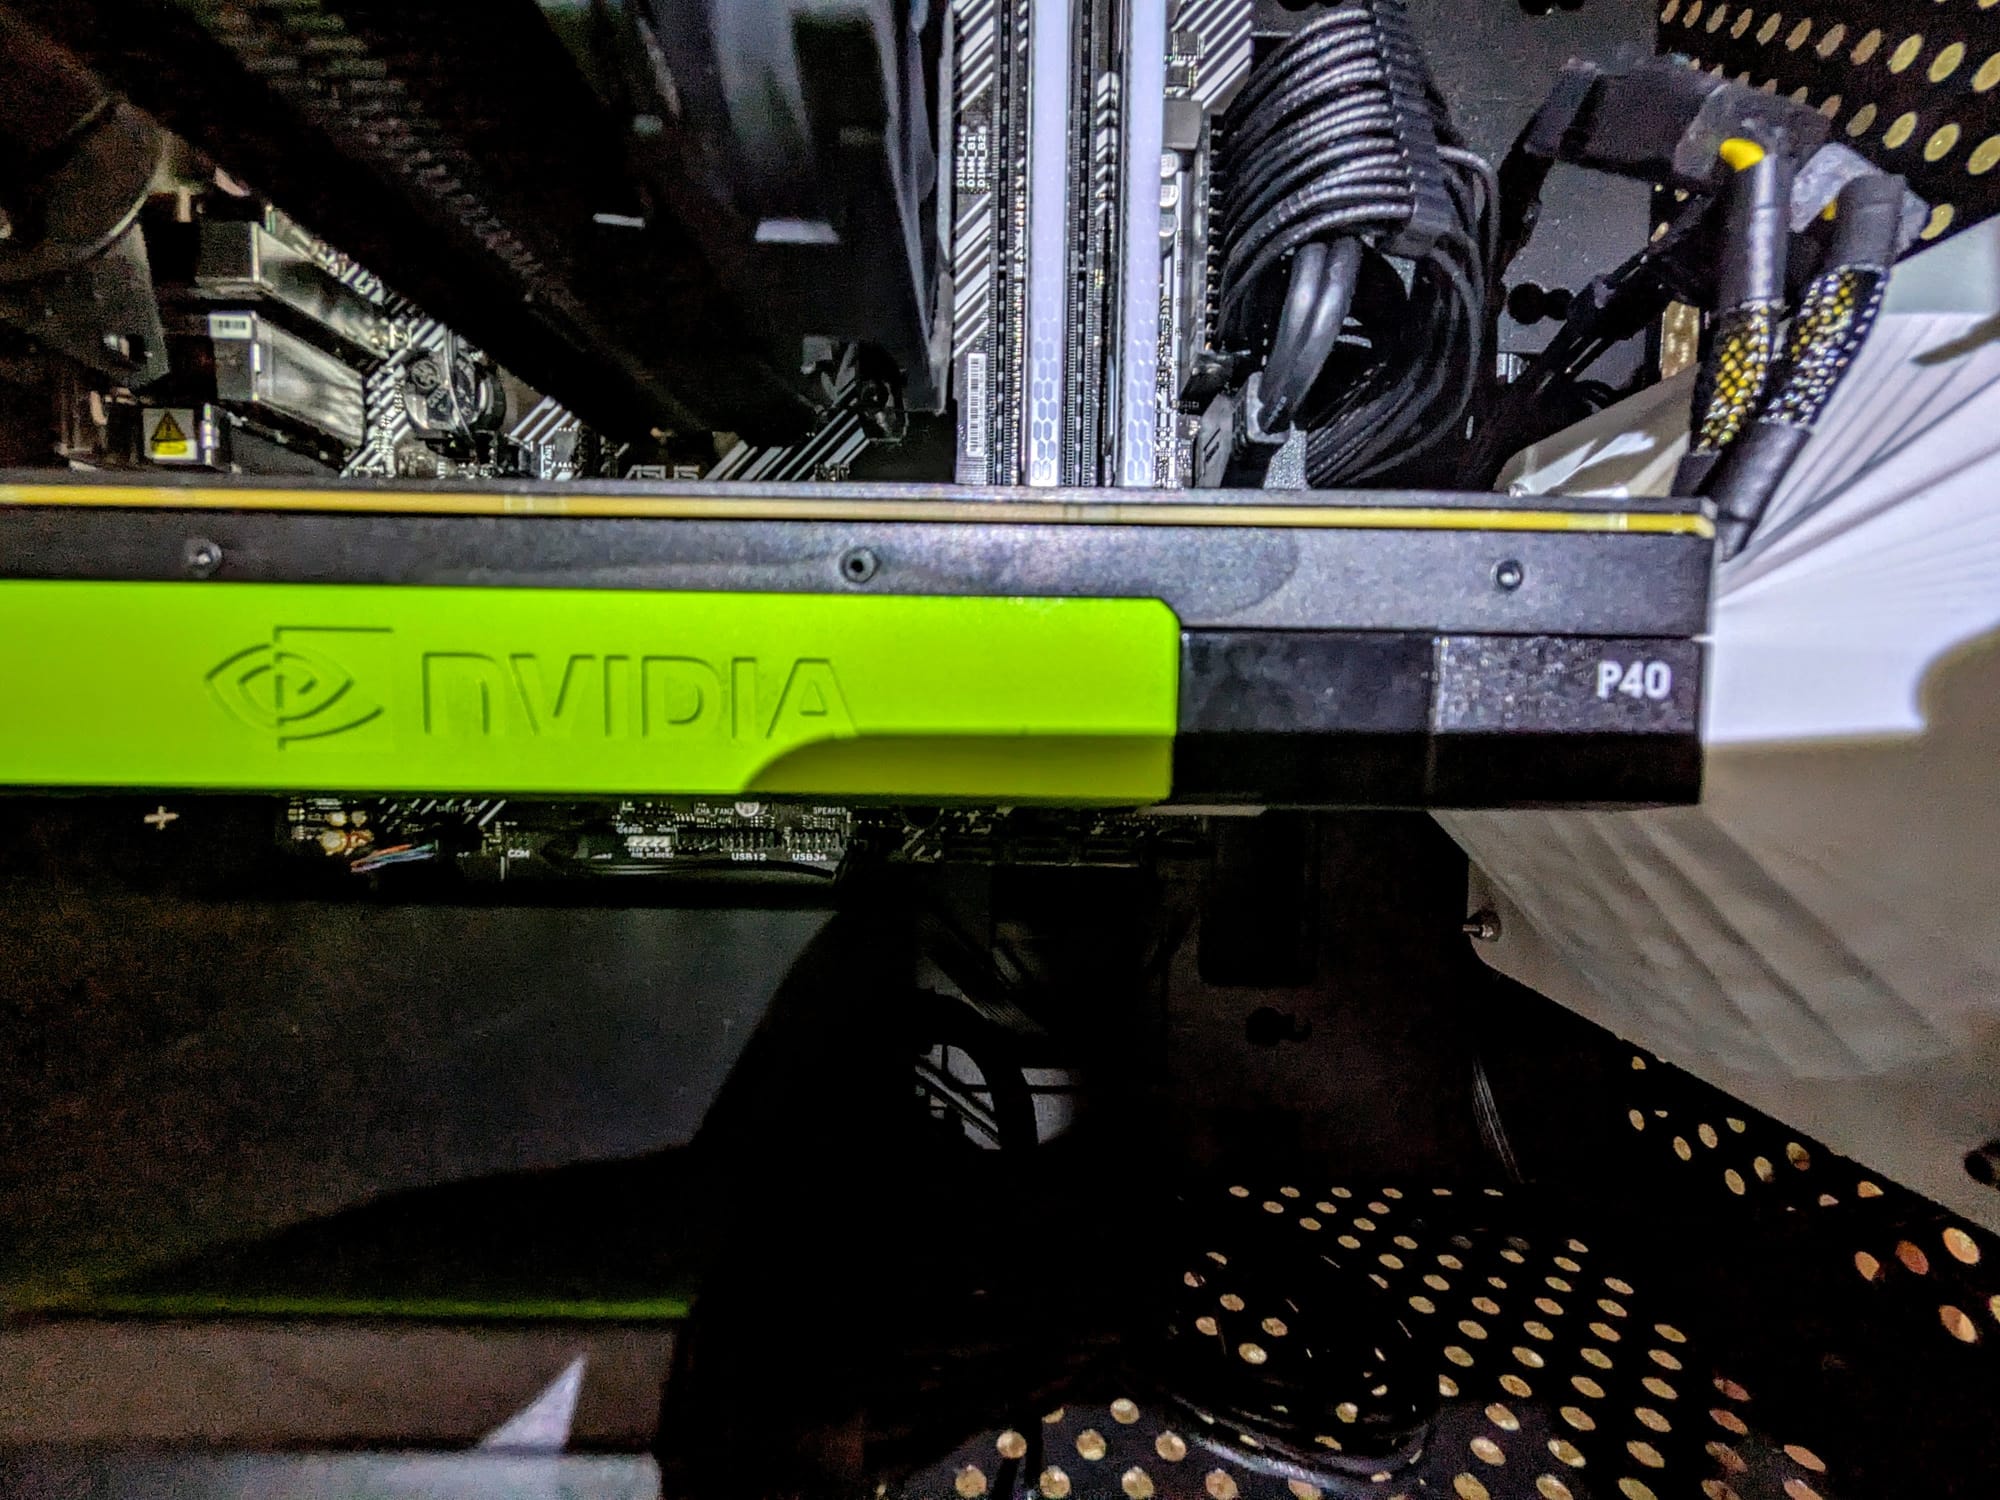
The NVIDIA Tesla P40 is a server/datacenter GPU from a few years ago. It’s not designed for gaming, but it has 24GB of VRAM: which is the main thing that matters for running large AI models locally. VRAM is like a brain: bigger = smarter. That much memory lets you run bigger models and longer conversations without constantly spilling over into system RAM and slowing everything down.
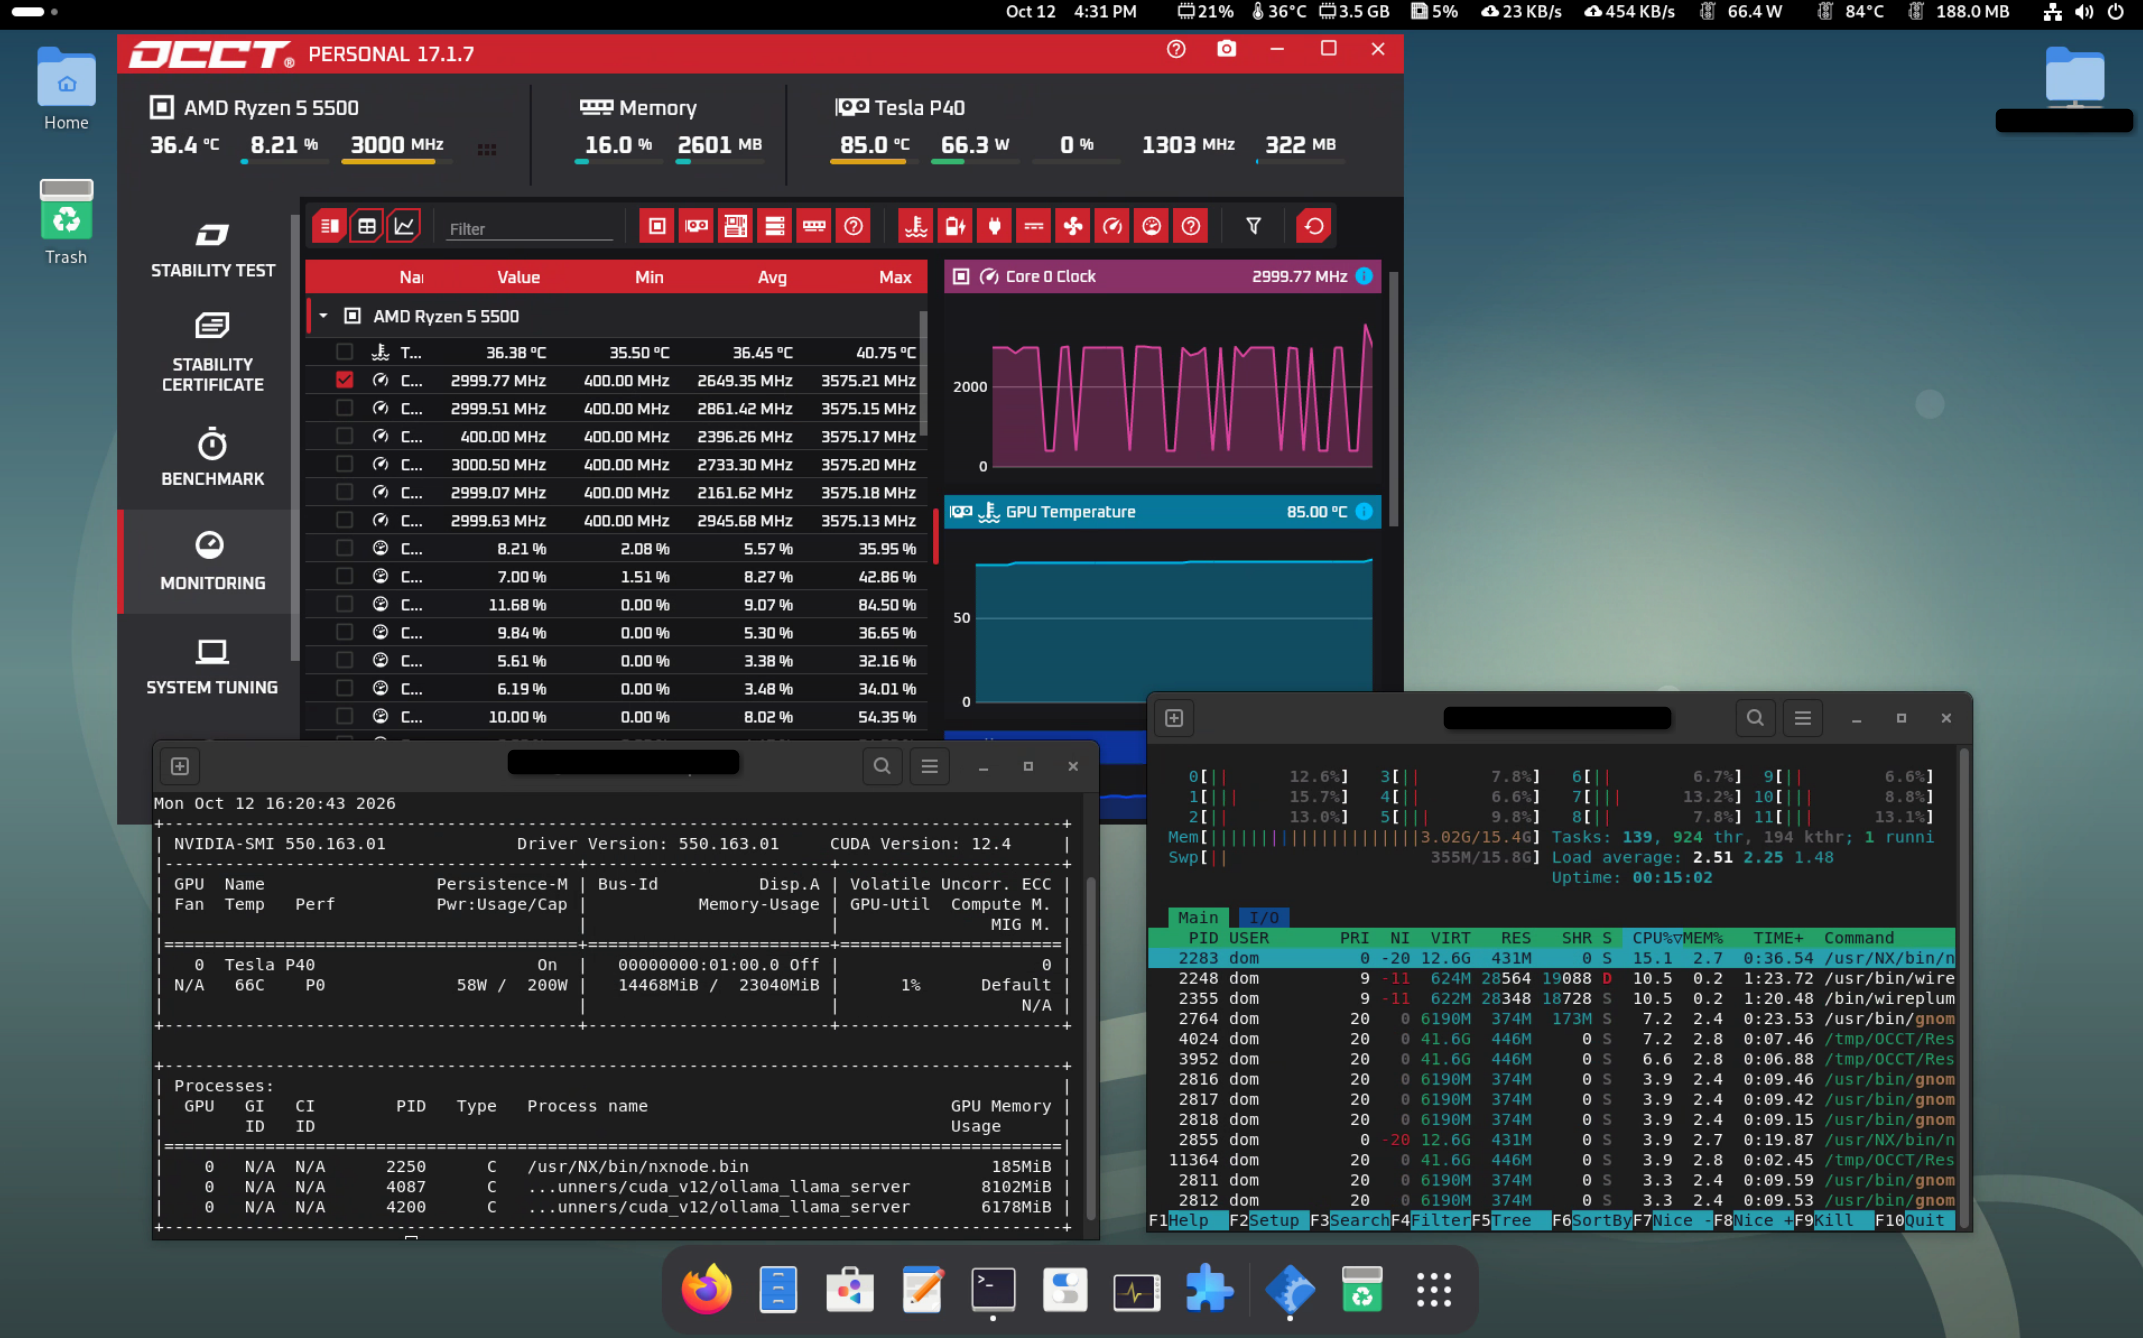
This is a mini-ITX headless (no desktop monitor plugged in, I connect to it remotely when I need to) Debian 13 box that’s basically a gaming-PC's cousin with a very specific job: running big local models on a 24GB NVIDIA Tesla P40. The worlds of gaming hardware and local inference are almost identical.
Specs:
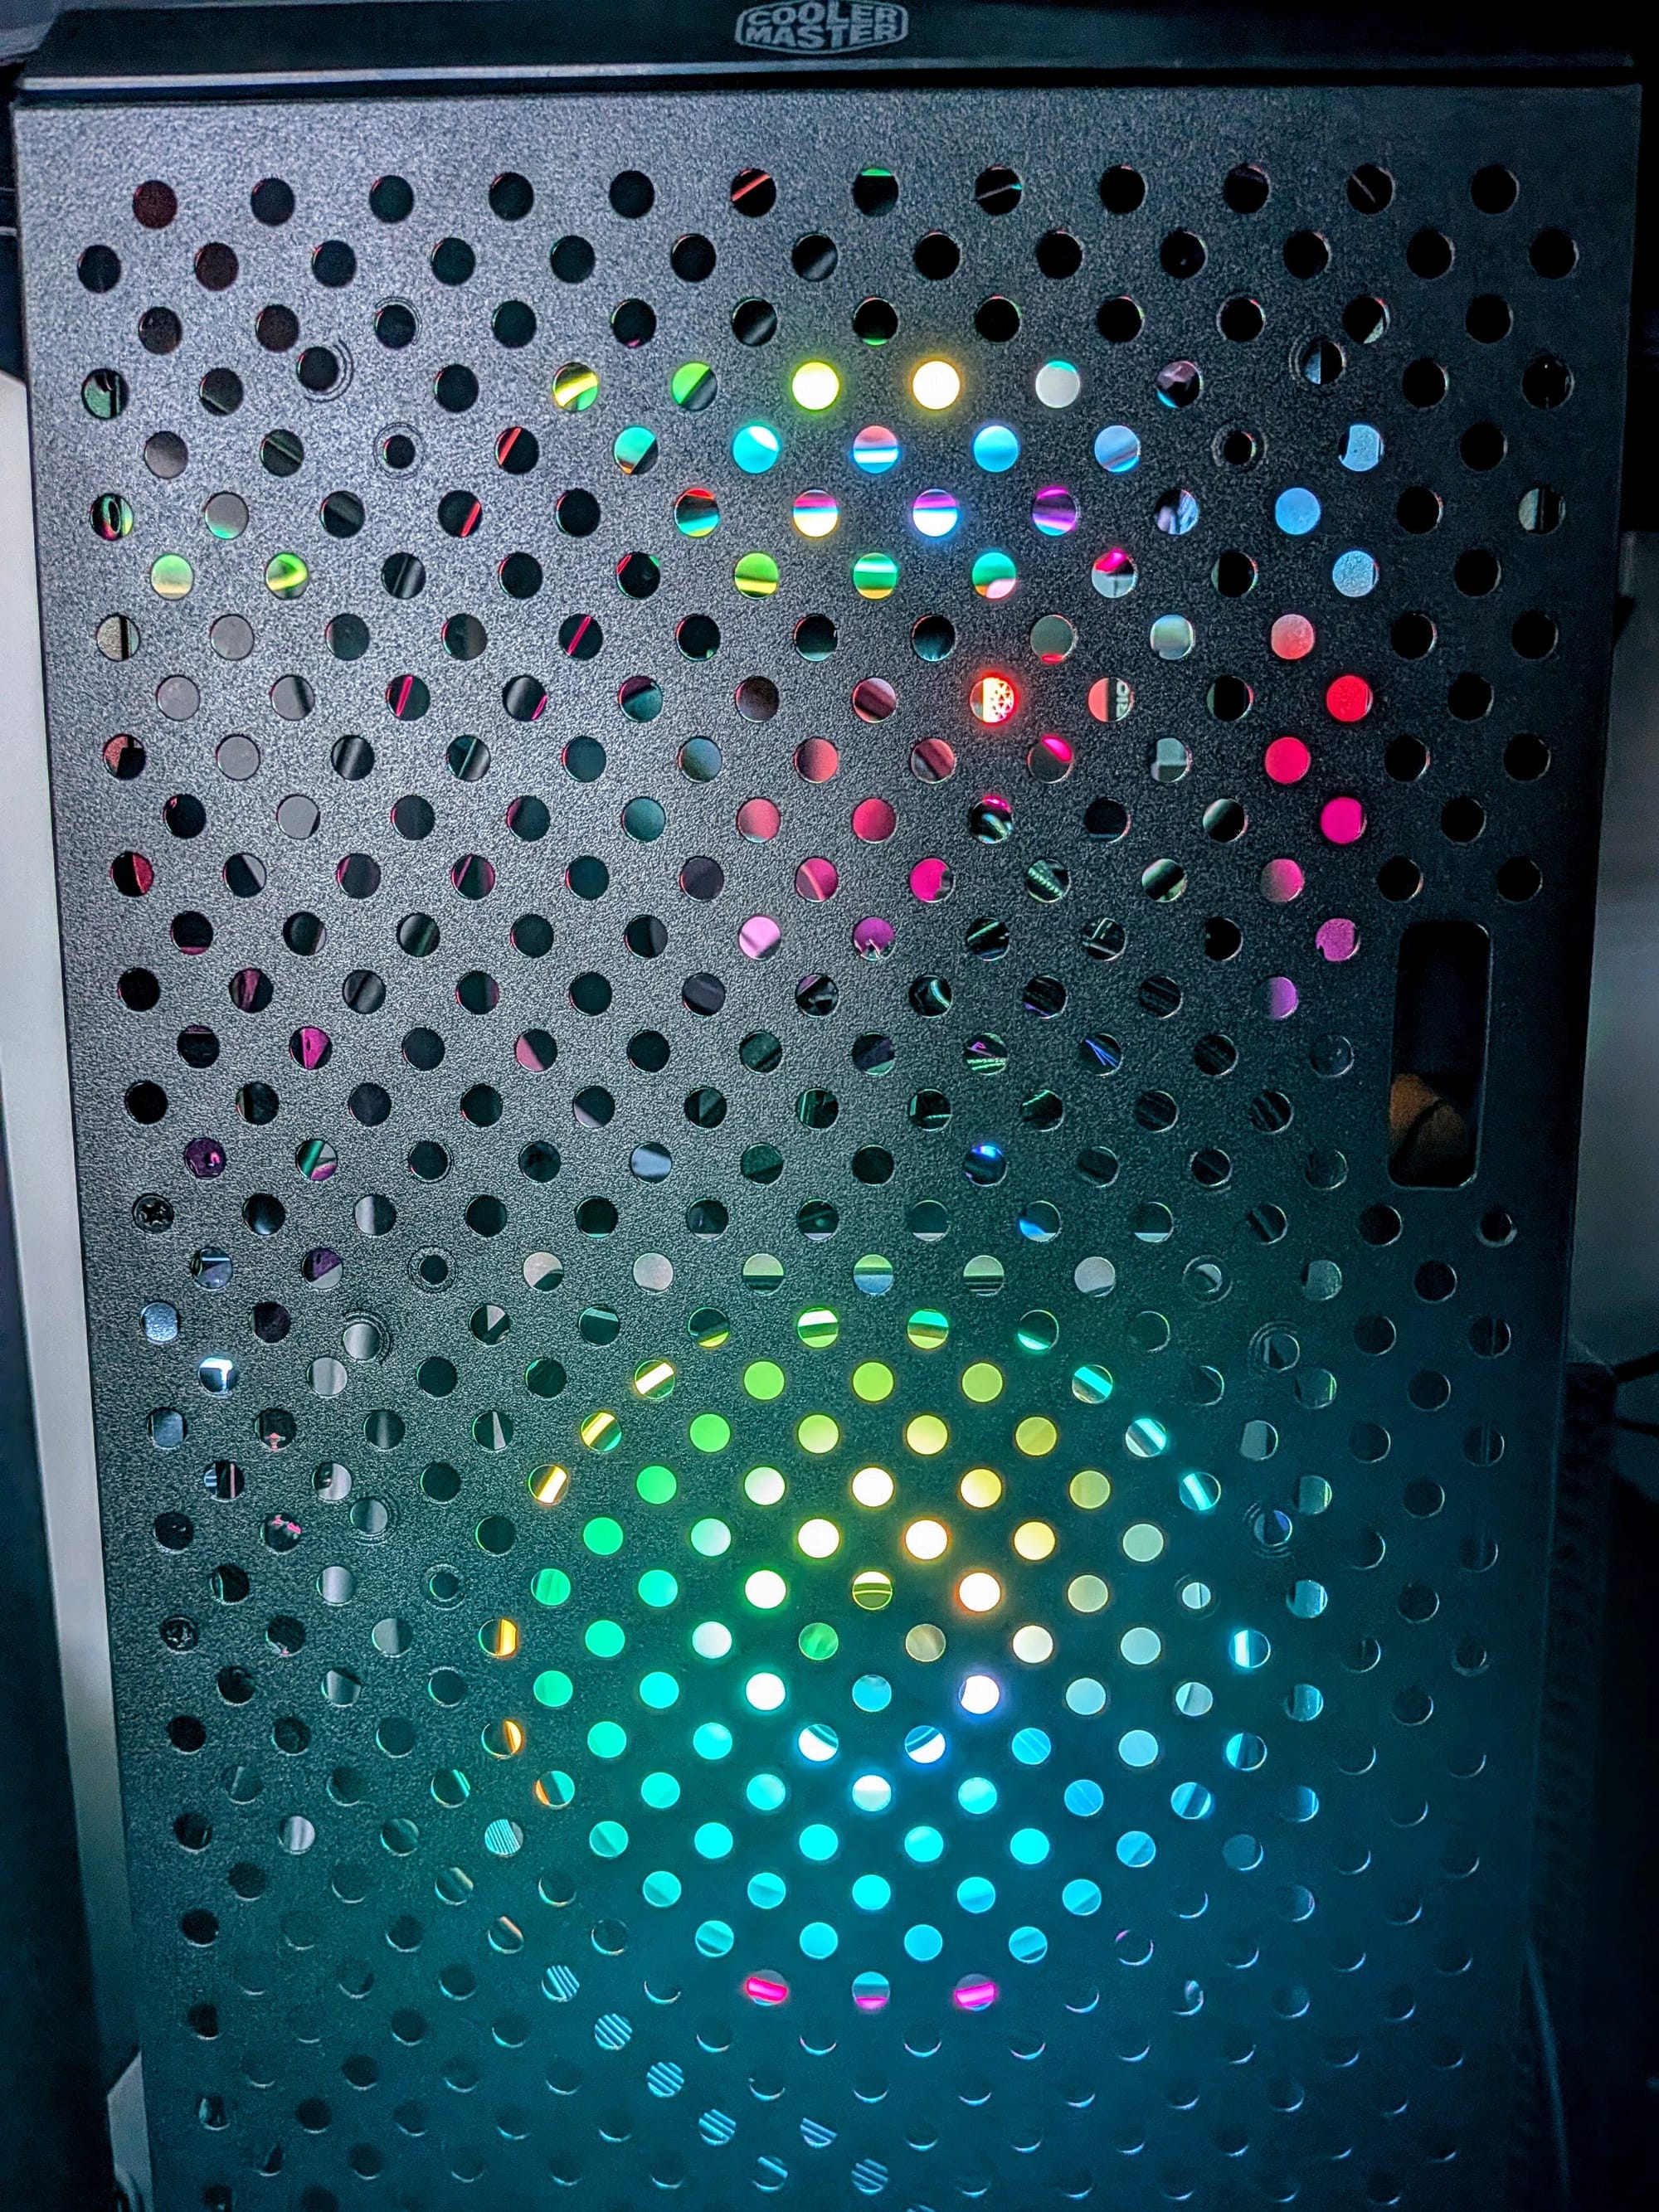
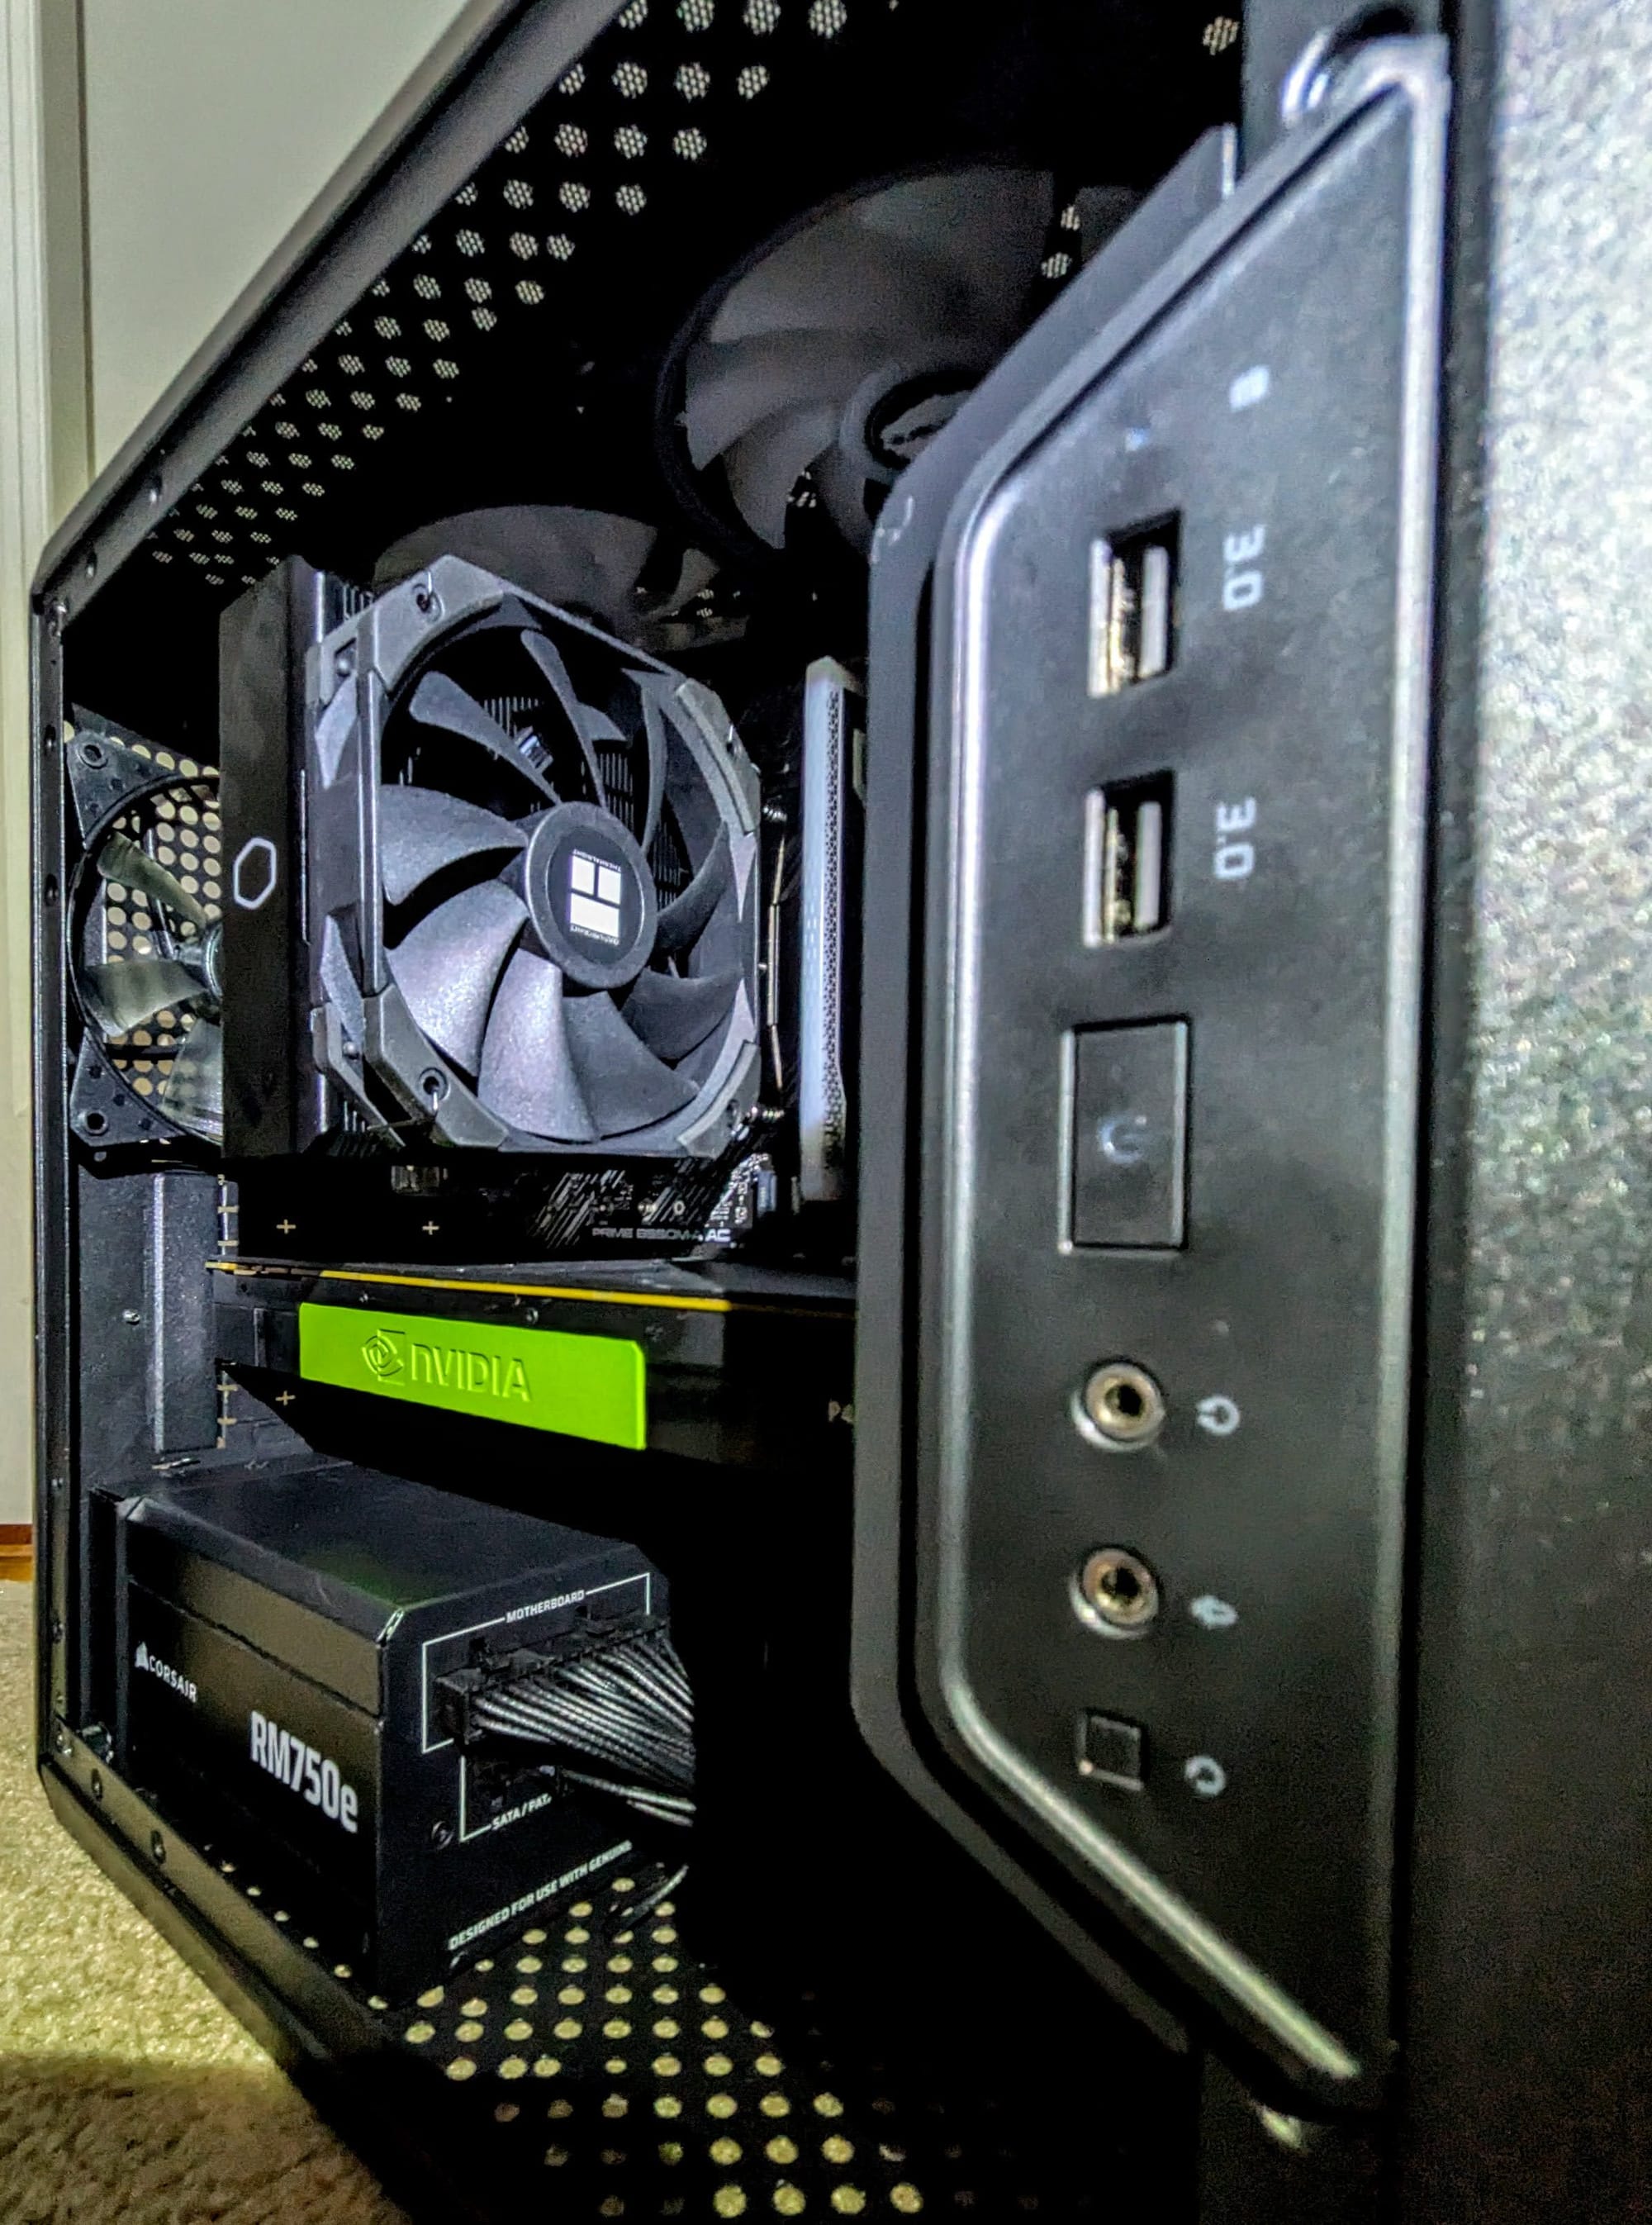
Cooler Master Q300L V1 Micro ATXcase - $26- Perfect case IMO. Not too tight but not too bulky and this case has a see through glass panel on the side where you can see all the internals!
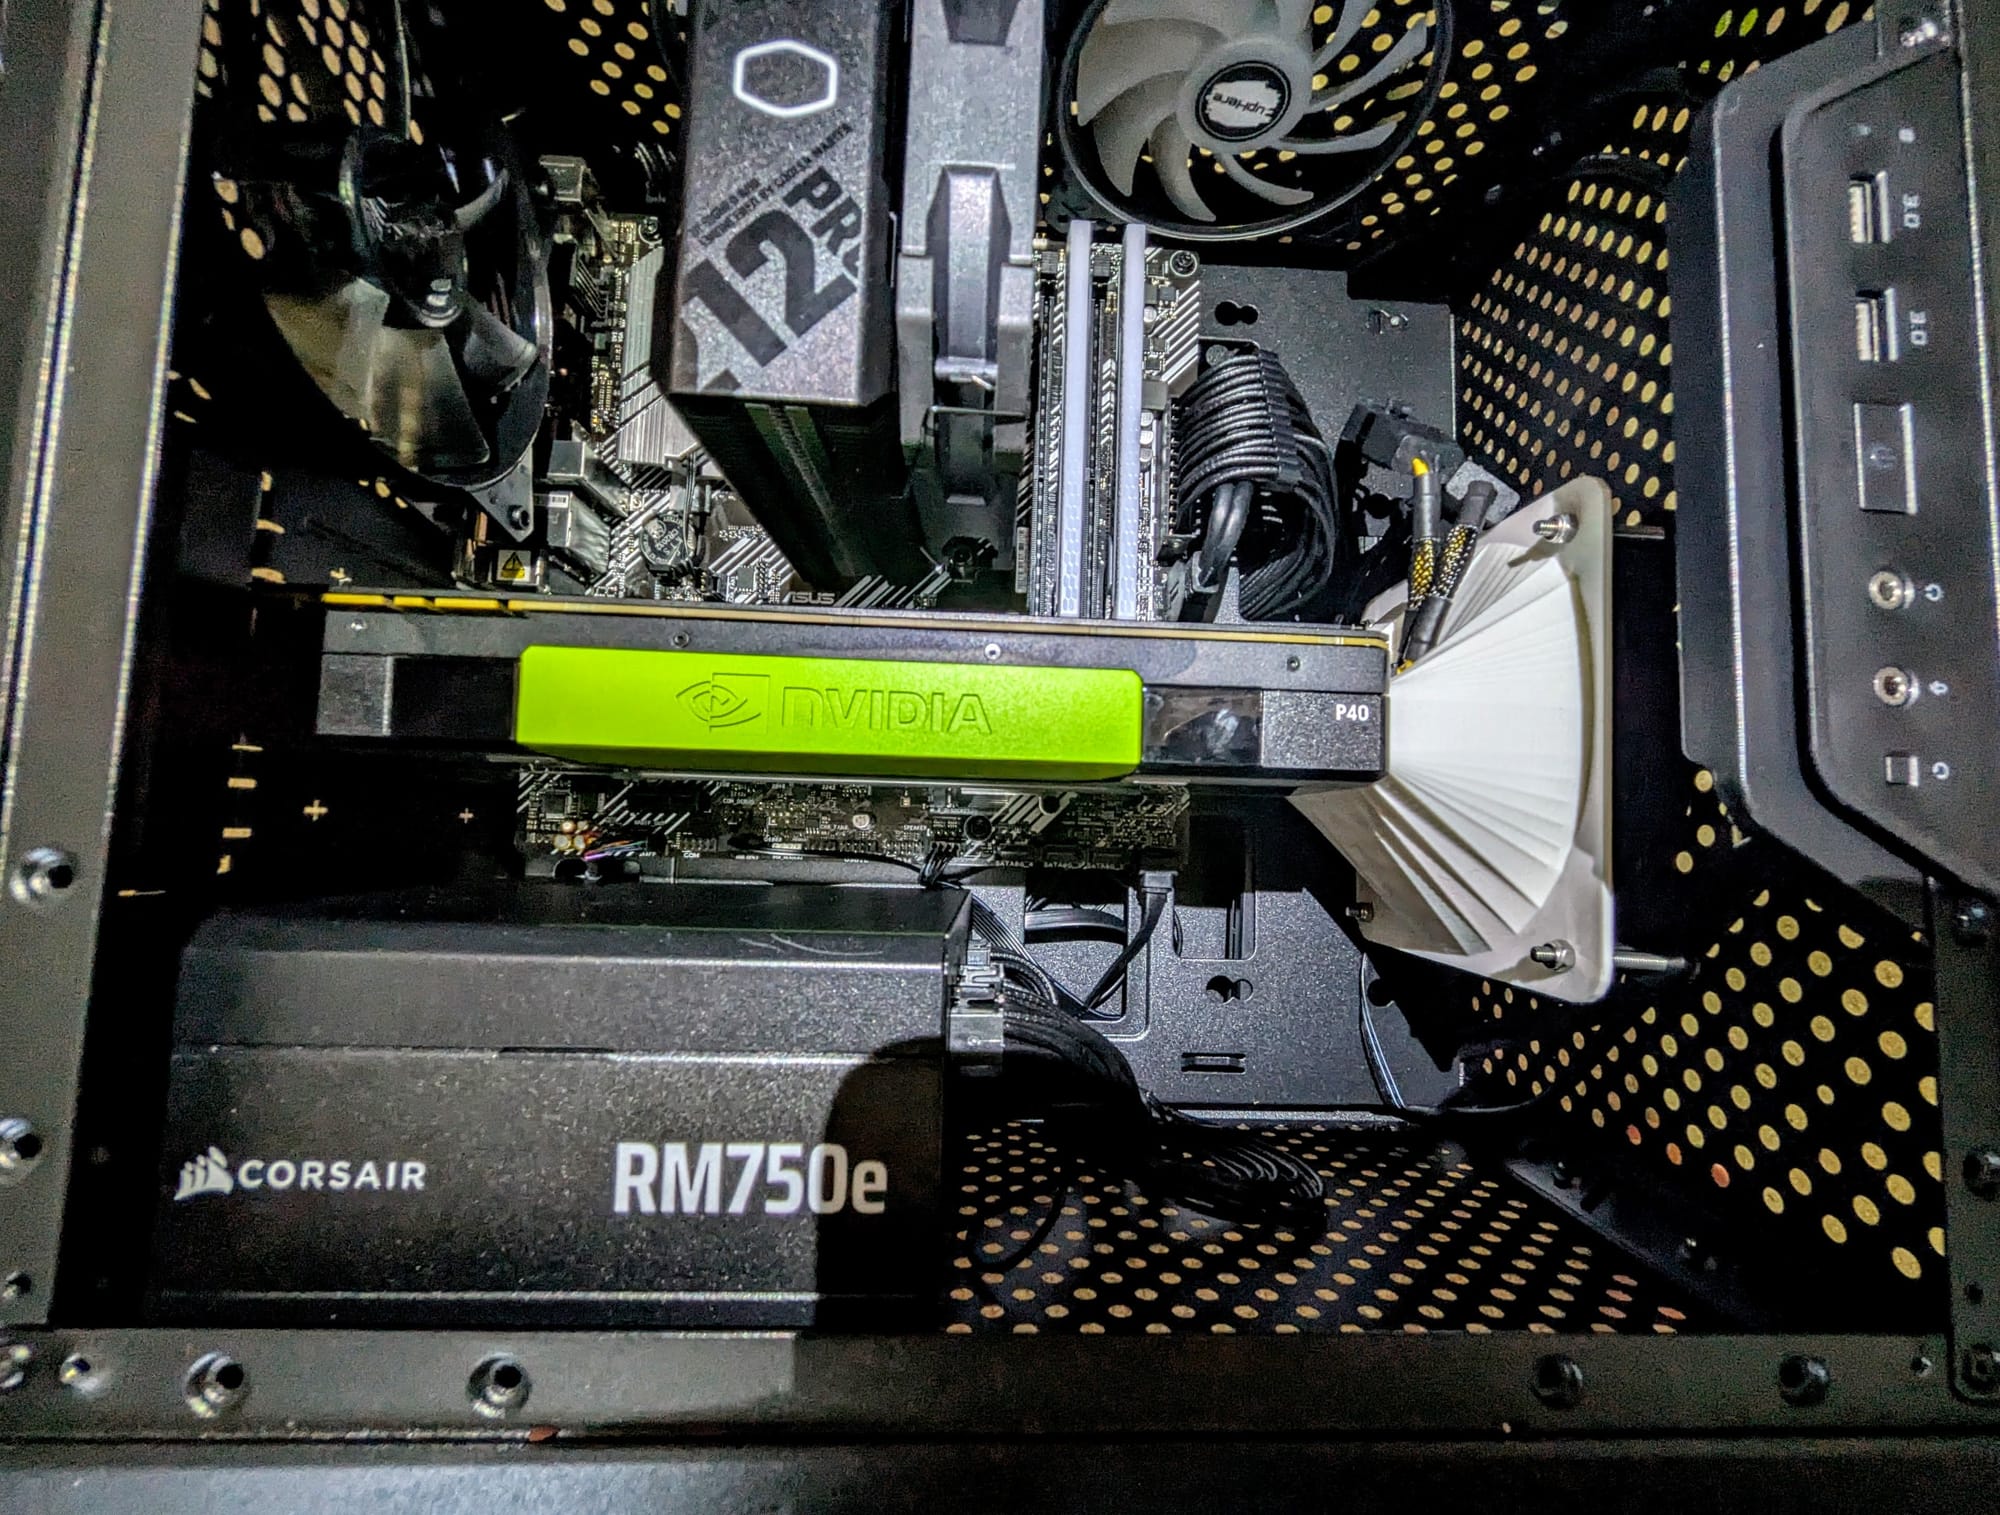
AMD Ryzen 5 5500(AM4 Platform) - (motherboard, ram, and CPU kit) - $25016GB RAMNVIDIA Tesla P40 24GB(Pascal still punches above its weight for VRAM-hungry workloads) - $300- Custom
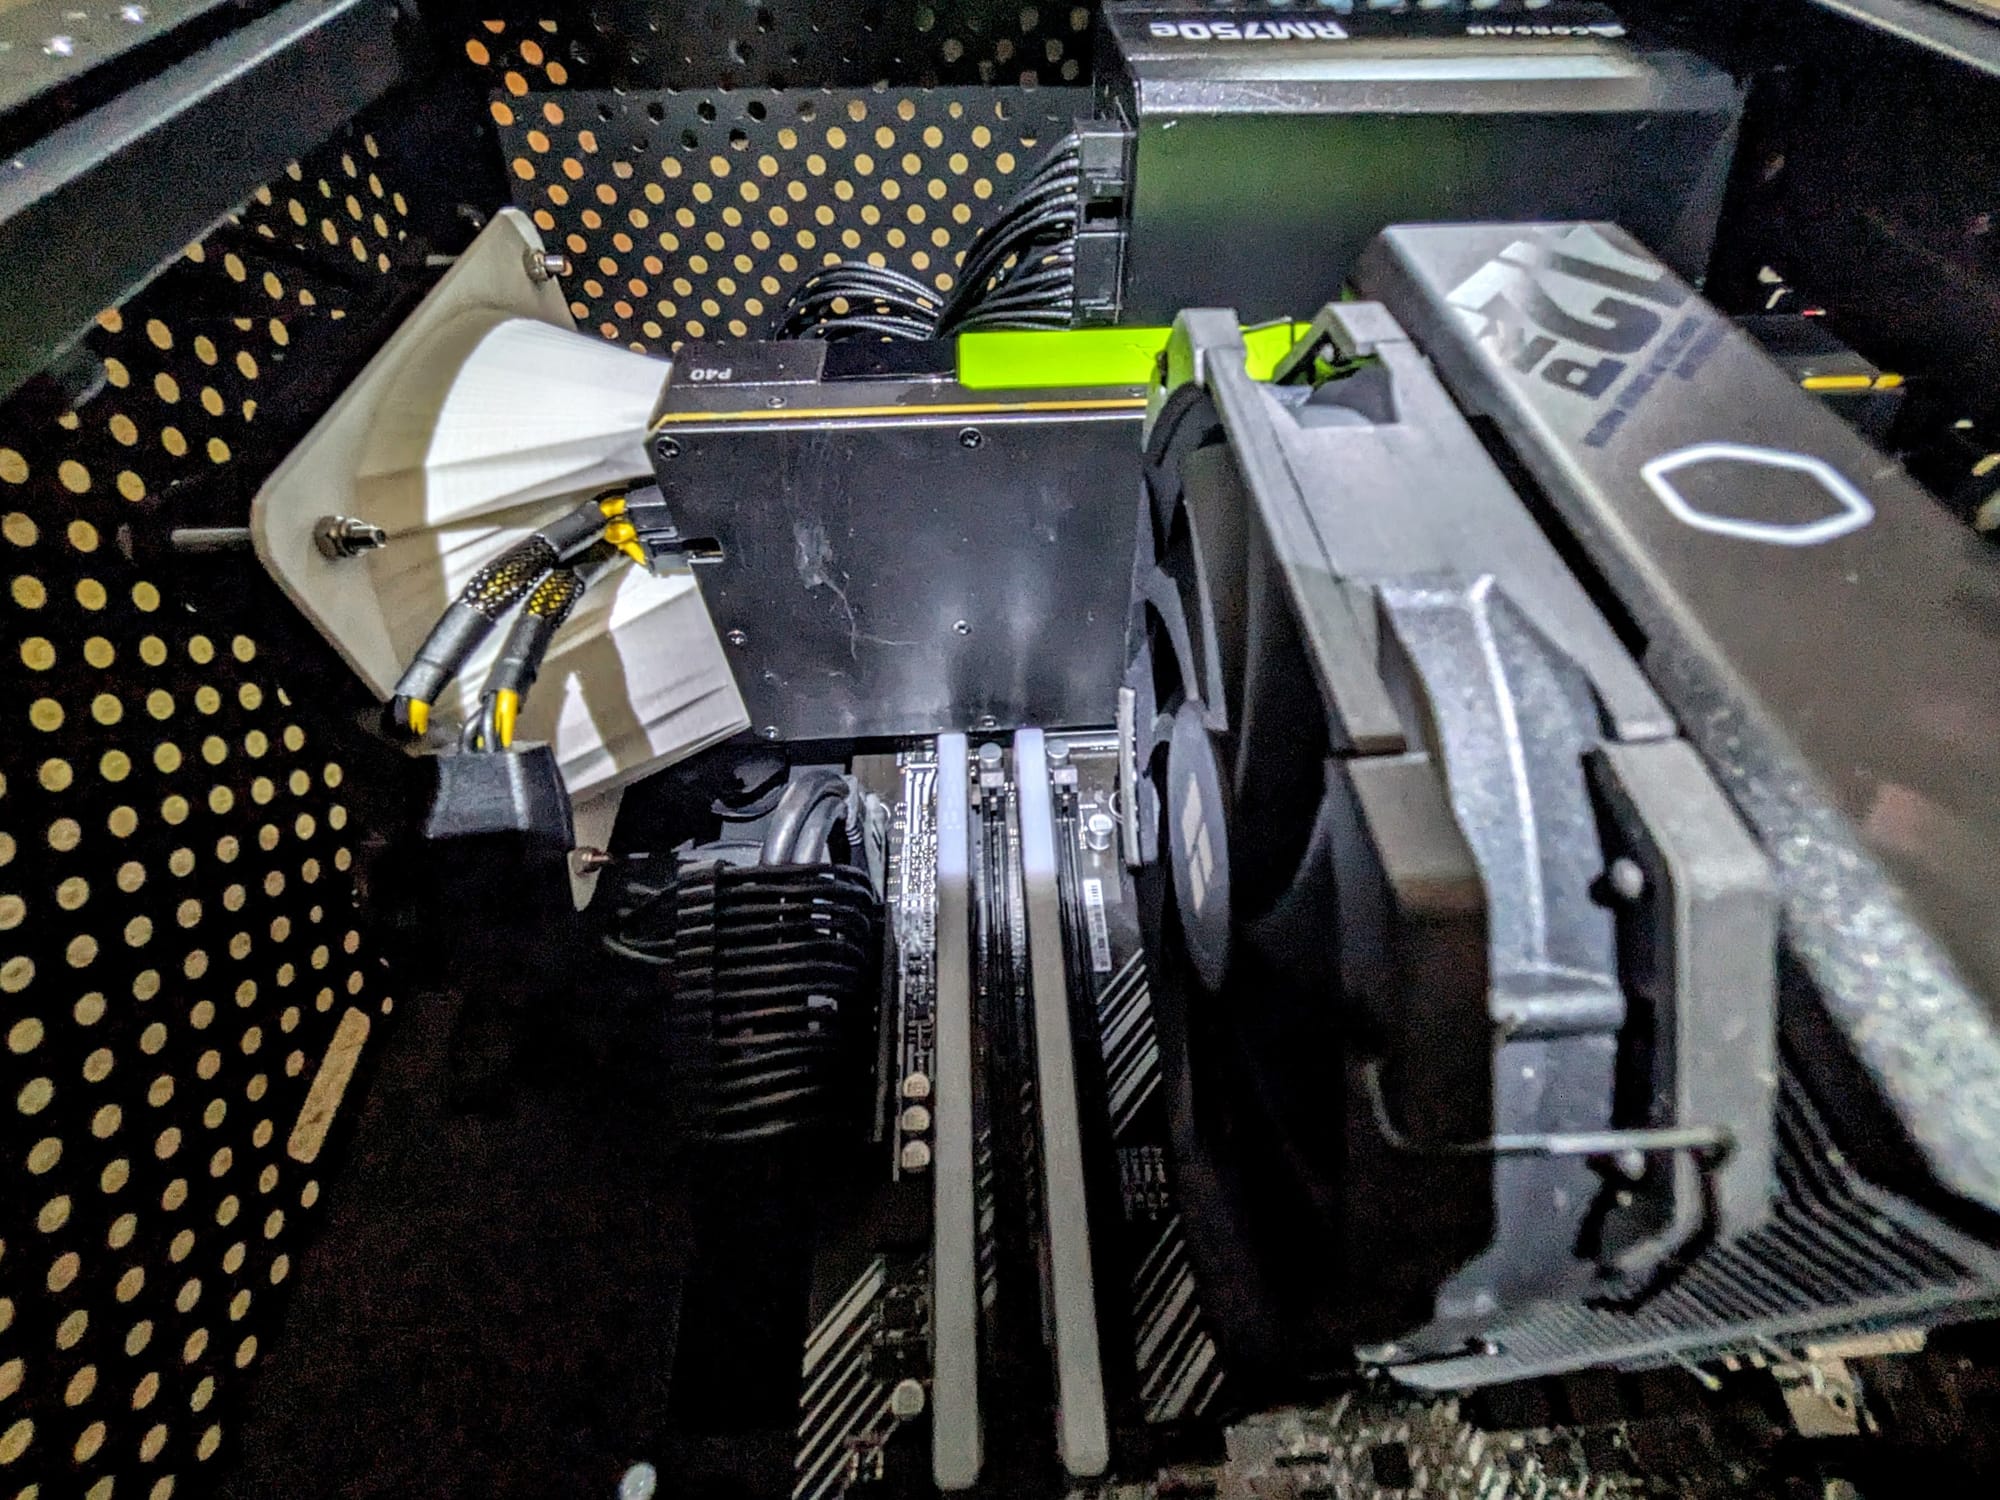
3D-printed fan hood+120mmfan. P40 has ZERO fans for cooling (AKA Passive Cooling) which is designed for server racks.
- Custom
- Headless
Debian 13, but as you can see in the last screenshot: I can still remote on with a GUI - $Free.99 - Temporary
NVIDIA GTX 1060was used just for initial setup/display, then removed
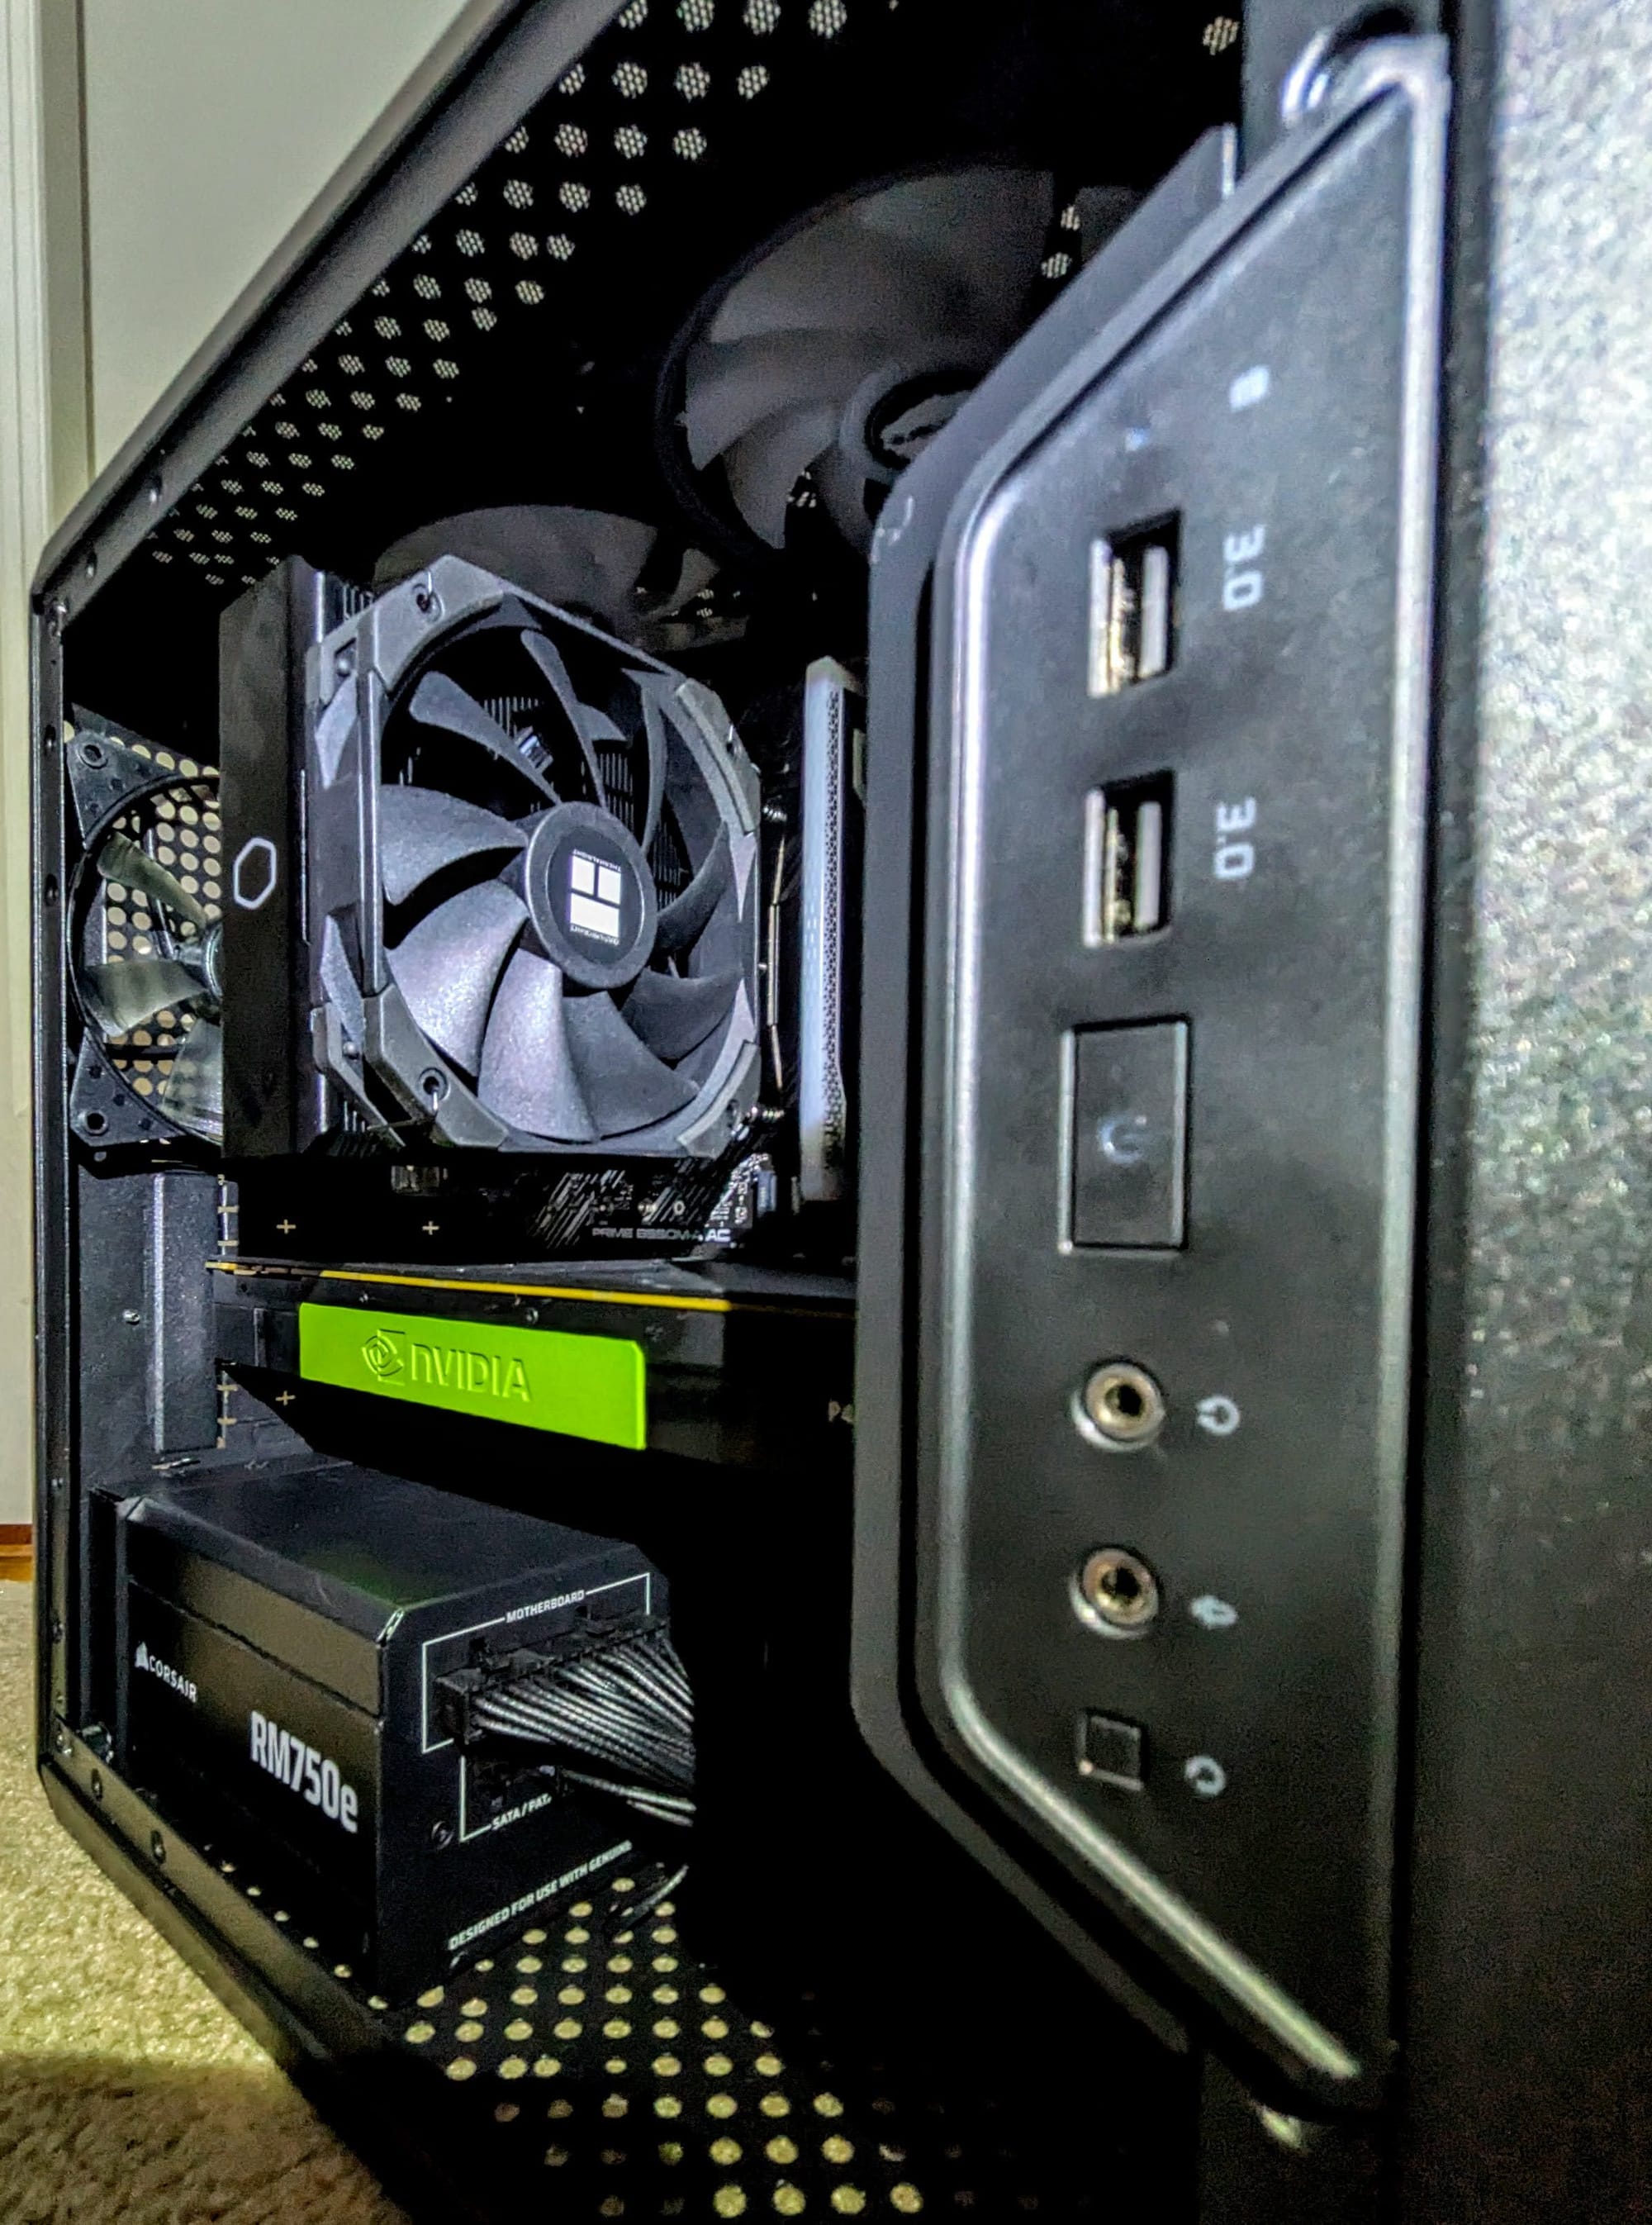
Previously, I built a similar AI box running an NVIDIA 4060 RTX 8GB. The P40’s 24GB is the star. it really opens up bigger models and longer context without immediately falling back to system RAM. Driver situation took a little patience (classic Pascal life), but once it was sorted I faced some cooling issues with a weak fan and BIOS settings with fan control. I can't really target the GPUs temps and adjust fan speed from the MB. So I caved and installed a spare Fan/LED Controller which upgraded the cooling. It was running at 90-93 C which it was throttling itself before. Now, it's quiet enough for the shelf, happy under sustained load, and hovers around 70 C (which is good enough!). I set the max watts from 250 -> 170 for now which never really hits with Ollama. The 24GB really shines with opening up my world to larger models but also and keeps more of the conversation in VRAM instead of spilling into system RAM.
Check out the photos of the case, cooling, and cable management. I didn't do the cleanest job like I normally do as I had to pull it apart quite a few times.
Lmk what you think, I'm curious what you all think of the build!
Any other local-inference or custom GPU builders here?
More photos of the build including ones in this post.